Natural language query (NLQ) lets a user state a question in business language.
Before building a query plan, identify the metric, population, time window, level of detail, comparison, and tenant data the query may use.
Before showing an answer, check that it answers the intended question, respects permissions, computes the result correctly, and includes evidence the user can inspect.
Define the Requirements for an NLQ Answer
In this article, an analytics interface that accepts questions in ordinary language and interprets them using approved business definitions. It builds a query plan the user is authorized to run and shows the result with enough context and evidence for the user to judge what was answered.
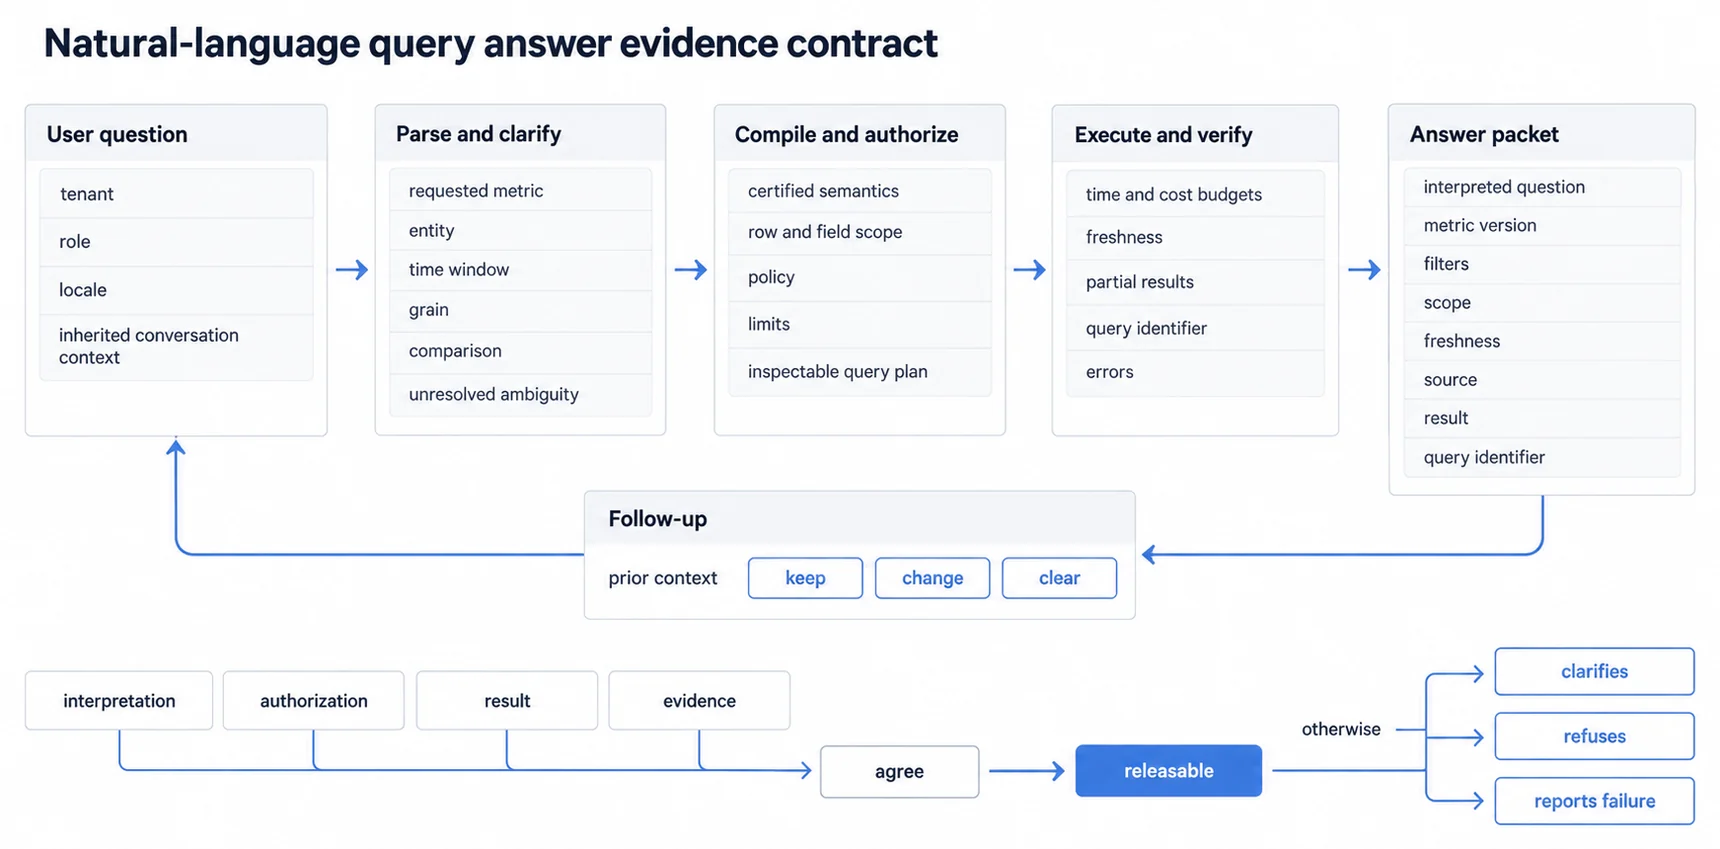
When adding NLQ to an embedded analytics product, plan how it will use metric governance, access control, query execution, and result design. Apply each user's tenant, role, and field permissions to the result, and show which scope was applied.
Before implementation, define which questions the feature is intended to answer, which it must clarify, and which it must refuse.
Turn Language Into an Explicit Interpretation
Consider the question: “Show revenue trends.” A usable interpretation still needs to resolve:
- which certified revenue metric and version;
- gross, net, recognized, booked, or another business definition;
- which entities and eligible population;
- event time or accounting period;
- default time window, grain, currency, and timezone;
- whether “trend” means values over time, change, or a comparison;
- which inherited filters from the current page or conversation remain active.
Let the language model propose values for these fields, but do not silently apply defaults that affect the answer. Ask a follow-up question when different interpretations could lead the user to different decisions. If a default can be used safely, display it in the interpreted question and let the user change it.
When evaluating AI-powered analytics features or other AI analytics capabilities, check whether you can trace each result to the user's question and the approved definitions used to answer it.
Bind Questions to Governed Semantics
Do not map “revenue” directly to a column name. Give the system the metric definition, join path, eligible set, aggregation, correction policy, currency treatment, and time grain it needs.
The semantic layer or equivalent governed model should provide:
- stable business names and aliases;
- certified metrics with owners and versions;
- permitted dimensions, joins, and aggregations;
- customer-specific mappings where the product supports them;
- validation rules for incompatible fields or grains;
- descriptions suitable for both the planner and the user-facing explanation.
Keep semantic retrieval scoped to the authenticated product context. A model should not receive every tenant's schema, sample values, or hidden field descriptions merely because they might improve generation.
Why can text-to-SQL fail without a semantic model?
A model that sees only table and column names has to infer what a semantic model would state outright: which column is the key, how two tables join, and at which grain a measure may be summed. When the inference is wrong, the query can still run and return a number that looks plausible.
Snowflake's engineering team uses a one-sale example. A customer buys four items in a single $100 sale. Join the customer to the sale, then the sale to its line items, and the sale total repeats once for every line item. Summed, it reports that the customer "spent $300 on four items, when in fact he spent $100" (Will Pugh, March 2026). Nothing in that SQL is invalid. The join path multiplied the measure before the aggregation ran.
On Spider 2.0, a set of 632 enterprise workflow tasks presented at ICLR 2025, the best agent solved 21.3% of tasks, against 91.2% on the older Spider 1.0 and 73.0% on BIRD. Average error rates were 29% to 49% for schema linking and 21% to 26% for joins in a 2024 survey of LLM text-to-SQL. In data.world's insurance benchmark (43 questions, 13 tables), GPT-4 answered 16.7% correctly from raw SQL, and 0% of the questions that combined simple wording with a complex schema.
A semantic model declares the joins and keys the language model would otherwise have to infer. In dbt's semantic models, every join-key column carries an entity type: primary, foreign, unique or natural. A Snowflake semantic view lists the relationships that define how its logical tables join. In Cube, "AI agents don't query the warehouse directly"; they query the semantic layer instead.
Four benchmarks from dbt Labs, Cube, data.world and Snowflake reported higher answer accuracy with a semantic model:
| Study | Sample | Without a semantic model | With one |
|---|---|---|---|
| dbt Labs, April 2026 | 11 questions, each run 20 times, two current models | 84.1% to 90.0% on modeled questions | 98.2% to 100% |
| Cube authors, arXiv, April 2026 | 100 questions (99 scored), 3 models | 45.5% to 50.5% | 67.7% to 68.7% (semantic model given as text context) |
| data.world, November 2023 | 43 questions, GPT-4 | 16.7% | 54.2% (knowledge graph) |
| Snowflake, August 2024 | internal question set | single-prompt GPT-4o | "nearly 2x as accurate" |
Compare gains within each benchmark: Cube, data.world and Snowflake ran or co-authored their studies using different datasets and baselines. In dbt's run with current models, accuracy rose by about 8 percentage points (90.0% to 98.2%); in data.world's older GPT-4 run, it roughly tripled (16.7% to 54.2%). Measure the improvement on your product's own questions before setting an accuracy target.
In dbt's 2026 run, the semantic layer declined questions its model did not cover, while text-to-SQL answered them, sometimes wrongly. When the product cannot answer a question, explain why and help the user ask one it can answer; the evidence packet below shows how. Define the semantic model before adding the language interface. To use one semantic model across many customers, see the semantic layer guide for embedded analytics.
What is text-to-SQL in an embedded analytics product?
Text-to-SQL is one way to build AI analytics features into a product. A language model turns a question such as "revenue by plan last quarter" into a SQL statement that a database then runs. The rest of this section is written for a customer-facing analytics product.
Google Cloud's engineers say a model needs significant amounts of knowledge to write accurate SQL, including what the schema looks like and what a column means for the business (Per Jacobsson, May 2025). A product serving many customers also needs tenant isolation, enforced outside the model.
Three text-to-SQL patterns compared
The three patterns differ in how they handle errors and data access.
| Pattern | Documented behavior |
|---|---|
| The model writes SQL against raw tables | dbt Labs: "failure looks like a plausible but incorrect answer". Cockroach Labs: a dynamically built query can lose the tenant filter. In tests of seven LLMs, unsanitized prompts led to SQL injection attacks |
| The model writes SQL from a semantic model | Snowflake Cortex Analyst uses the semantic model's metadata only to generate SQL, and integrates with Snowflake's role-based access control |
| The model queries through a semantic layer | dbt Labs: with the semantic layer, failure looks like an error message |
In our view, an error message is the safer failure when the customer will not check the SQL. In dbt's run, the semantic layer also declined questions its model did not cover, so a product using the third pattern needs a way to tell the customer what it can answer.
Constraining the SQL a text-to-SQL model writes
We recommend these controls, which follow the least-privilege principle in OWASP's guidance on excessive agency:
- Give the model the calling customer's metrics, dimensions and relationships from the semantic layer, instead of the raw schema.
- Allow read-only statements against a fixed list of objects, with a row limit and a timeout. Fix values such as the user ID in the query layer instead of leaving them to the model.
- Validate each statement before it runs, and reject it if it fails validation instead of repairing it silently.
Tenant scoping in a text-to-SQL pipeline
Enforce tenant isolation outside the model, as these production systems do:
- PAR Technology on AWS (June 2026). The authenticated session's key generates filters that restrict the warehouse tables to that user's rows before the model is invoked. The authors write that "No user input influences it. No LLM output influences it."
- Databricks Genie. Data access is evaluated using each end user's own Unity Catalog permissions.
- Snowflake Cortex Analyst. The generated SQL runs under Snowflake's role-based access control.
If the database enforces the boundary with row-level security, check which role runs the generated SQL. In PostgreSQL 18, superusers and roles with BYPASSRLS "always bypass the row security system", and table owners normally bypass it unless the table uses FORCE ROW LEVEL SECURITY. A service that runs generated SQL as the table owner needs that setting, or a different role.
How to evaluate text-to-SQL for a customer-facing product
Execution accuracy, the most widely used evaluation metric, still produces many false positives and negatives (NAACL, 2025). Databricks scores Genie by comparing result sets against a reference query, and suggests two to four phrasings per question.
We suggest two additions for a customer-facing product:
- Include questions the product should decline to answer, and check that it declines.
- Include questions that ask for another customer's data, by name, by ID and inside pasted instructions, and report the number of rows that leak. The pass mark is zero.
Authorize the Compiled Plan
Do not rely on prompt instructions such as “only query the current tenant.” Authorization belongs in trusted services after the question has been interpreted and before execution.
The compiled plan should bind:
- tenant, user, role, and allowed purpose where applicable;
- row, field, metric, and artifact permissions;
- approved datasets and join paths;
- time range, result size, complexity, and cost limits;
- export, drill-through, cache, and follow-up behavior;
- a policy version and audit identifier.
Apply these controls to the generated query or intermediate representation. The browser and the language model can pass the requested context, but neither should be able to expand the user's authorized data scope.
In a customer-facing analytics product, interpret each phrase using that customer's own data and business definitions.
Execute Within a Bounded Runtime
Set runtime limits per tenant and per question.
Use an intermediate representation or inspectable plan when possible, then validate it before generating database-specific SQL or another executable query. Enforce time, row, memory, and cost budgets. Restrict functions and data sources. Cancel abandoned requests. Run interactive queries separately from heavy background jobs when they need different amounts of processing power or memory.
Return distinct states for:
- no matching data;
- a valid zero;
- stale or delayed data;
- partial results;
- a refused question;
- a timeout or resource limit;
- an execution or source failure.
Show the result state explicitly and keep any explanation grounded in it.
Return an Evidence Packet With Every Answer
The answer should expose enough context for the user to judge what the system did:
- the interpreted question;
- metric name and version or definition access;
- active filters, tenant or entity scope, time window, grain, and comparison;
- data freshness and relevant source status;
- the result and its empty, partial, stale, or failed state;
- a query or audit identifier for support and investigation.
Choose the chart only after the result has passed these checks.
Preserve the answer's scope and interpretation when users drill into it, download it, save it, or share a link to it.
Make Follow-Up Context Visible
In conversational analytics, check every follow-up question for context carried over from earlier turns.
Suppose the user asks “Show net revenue by region for Q4,” then follows up with “now by product.” Decide whether to keep or change the metric, Q4 window, region filter, currency, tenant, and comparison, and show what was kept and what changed before or with the result.
Model conversational state as structured fields rather than only as chat history. Each turn should explicitly keep, change, or clear the metric, entities, filters, time window, grain, and comparison. Reauthorize and revalidate every new plan.
NLQ vs Dashboard Controls: When to Use Each
Use NLQ when users ask varied questions and the product can interpret their business terms with approved definitions and show how it understood each question. Use dashboard controls for repeated monitoring, precise parameter changes, comparisons between known views, and situations where typing is inconvenient.
Let users create or refine a query with NLQ, then adjust its metric, filters, and level of detail through dashboard controls. See also augmented analytics.
Self-service analytics users also need approved metrics and filters, a visible interpretation, ways to recover from errors, and access to support when the system cannot answer reliably.
Test With Realistic Questions and Failure Cases
Build an evaluation set from representative, permitted questions and score the stages separately:
- intent and entity extraction;
- metric and semantic mapping;
- clarification versus safe default selection;
- tenant, row, and field authorization;
- plan validity and bounded execution;
- numeric and categorical result correctness;
- evidence completeness;
- follow-up context retention and clearing;
- refusal and failure behavior.
Include ambiguous wording, synonyms, misspellings, conflicting context, hidden fields, cross-tenant attempts, large ranges, unsupported joins, delayed sources, corrections, empty results, and adversarial instructions. Retain the interpreted plan and query identifier for each failure.
Require human review in high-impact domains and when semantic definitions, policy, or model behavior change. Measure which questions produce clarification, refusal, correction, support contact, or abandonment, not only whether the interface generated an answer.
Release Requirements for an Answer
Before an embedded analytics product shows a natural-language answer, require four things: the question is bound to approved definitions, permissions are checked by trusted services, execution stays within limits, and the answer carries its evidence (the definitions used, the filters applied, the data freshness and a query identifier).
Where to go next
Ready to launch customer-facing analytics?
Stop losing customers to competitors with better analytics. Sumboard's customer-facing analytics platform lets you launch self-service dashboards in days, not months.